
- Status
- Verified
- Trending
- #26
- Downloads, 30 days
- 0
- Weights
- 52.9 GB
- Sources
- 2
- Revision
- Manifest
🧩 ModelScope · 🤗 Hugging Face · 📄 Blog · 🖥️ Demo 🎨 Design Skill · 📊 PPT Skill
At a glance
- Task
- Text to image
- Input
- text
- Output
- image
- Parameters
- 6.2B
- Precision
- BF16
- Format
- Safetensors
- Library
- custom
- License
- MITCommercial use
- Released
- Sep 2026
- Updated
- Sep 2026
- Likes
- 198
- Downloads, all time
- 0
Family
Models built on Ming-Image-0.1-Design.
Run it
Pinned to the indexed revision.
hf download inclusionAI/Ming-Image-0.1-Design --revision 208087ada1486931692c1896f38d4cd16ff3df82Through the hub: the same tools, each file from a source that is up (Hugging Face, ModelScope, IPFS), at this revision. The second line checks every file against its address.
export HF_ENDPOINT=https://gethologram.ai
cd "$(hf download inclusionAI/Ming-Image-0.1-Design --quiet)" && curl -s $HF_ENDPOINT/inclusionAI/Ming-Image-0.1-Design/resolve/main/SHA256SUMS | sha256sum -c --quiet
Spaces
Used in 2 Spaces.
Read the full model card
Ming-Image-0.1-Design
🧩 ModelScope · 🤗 Hugging Face · 📄 Blog · 🖥️ Demo
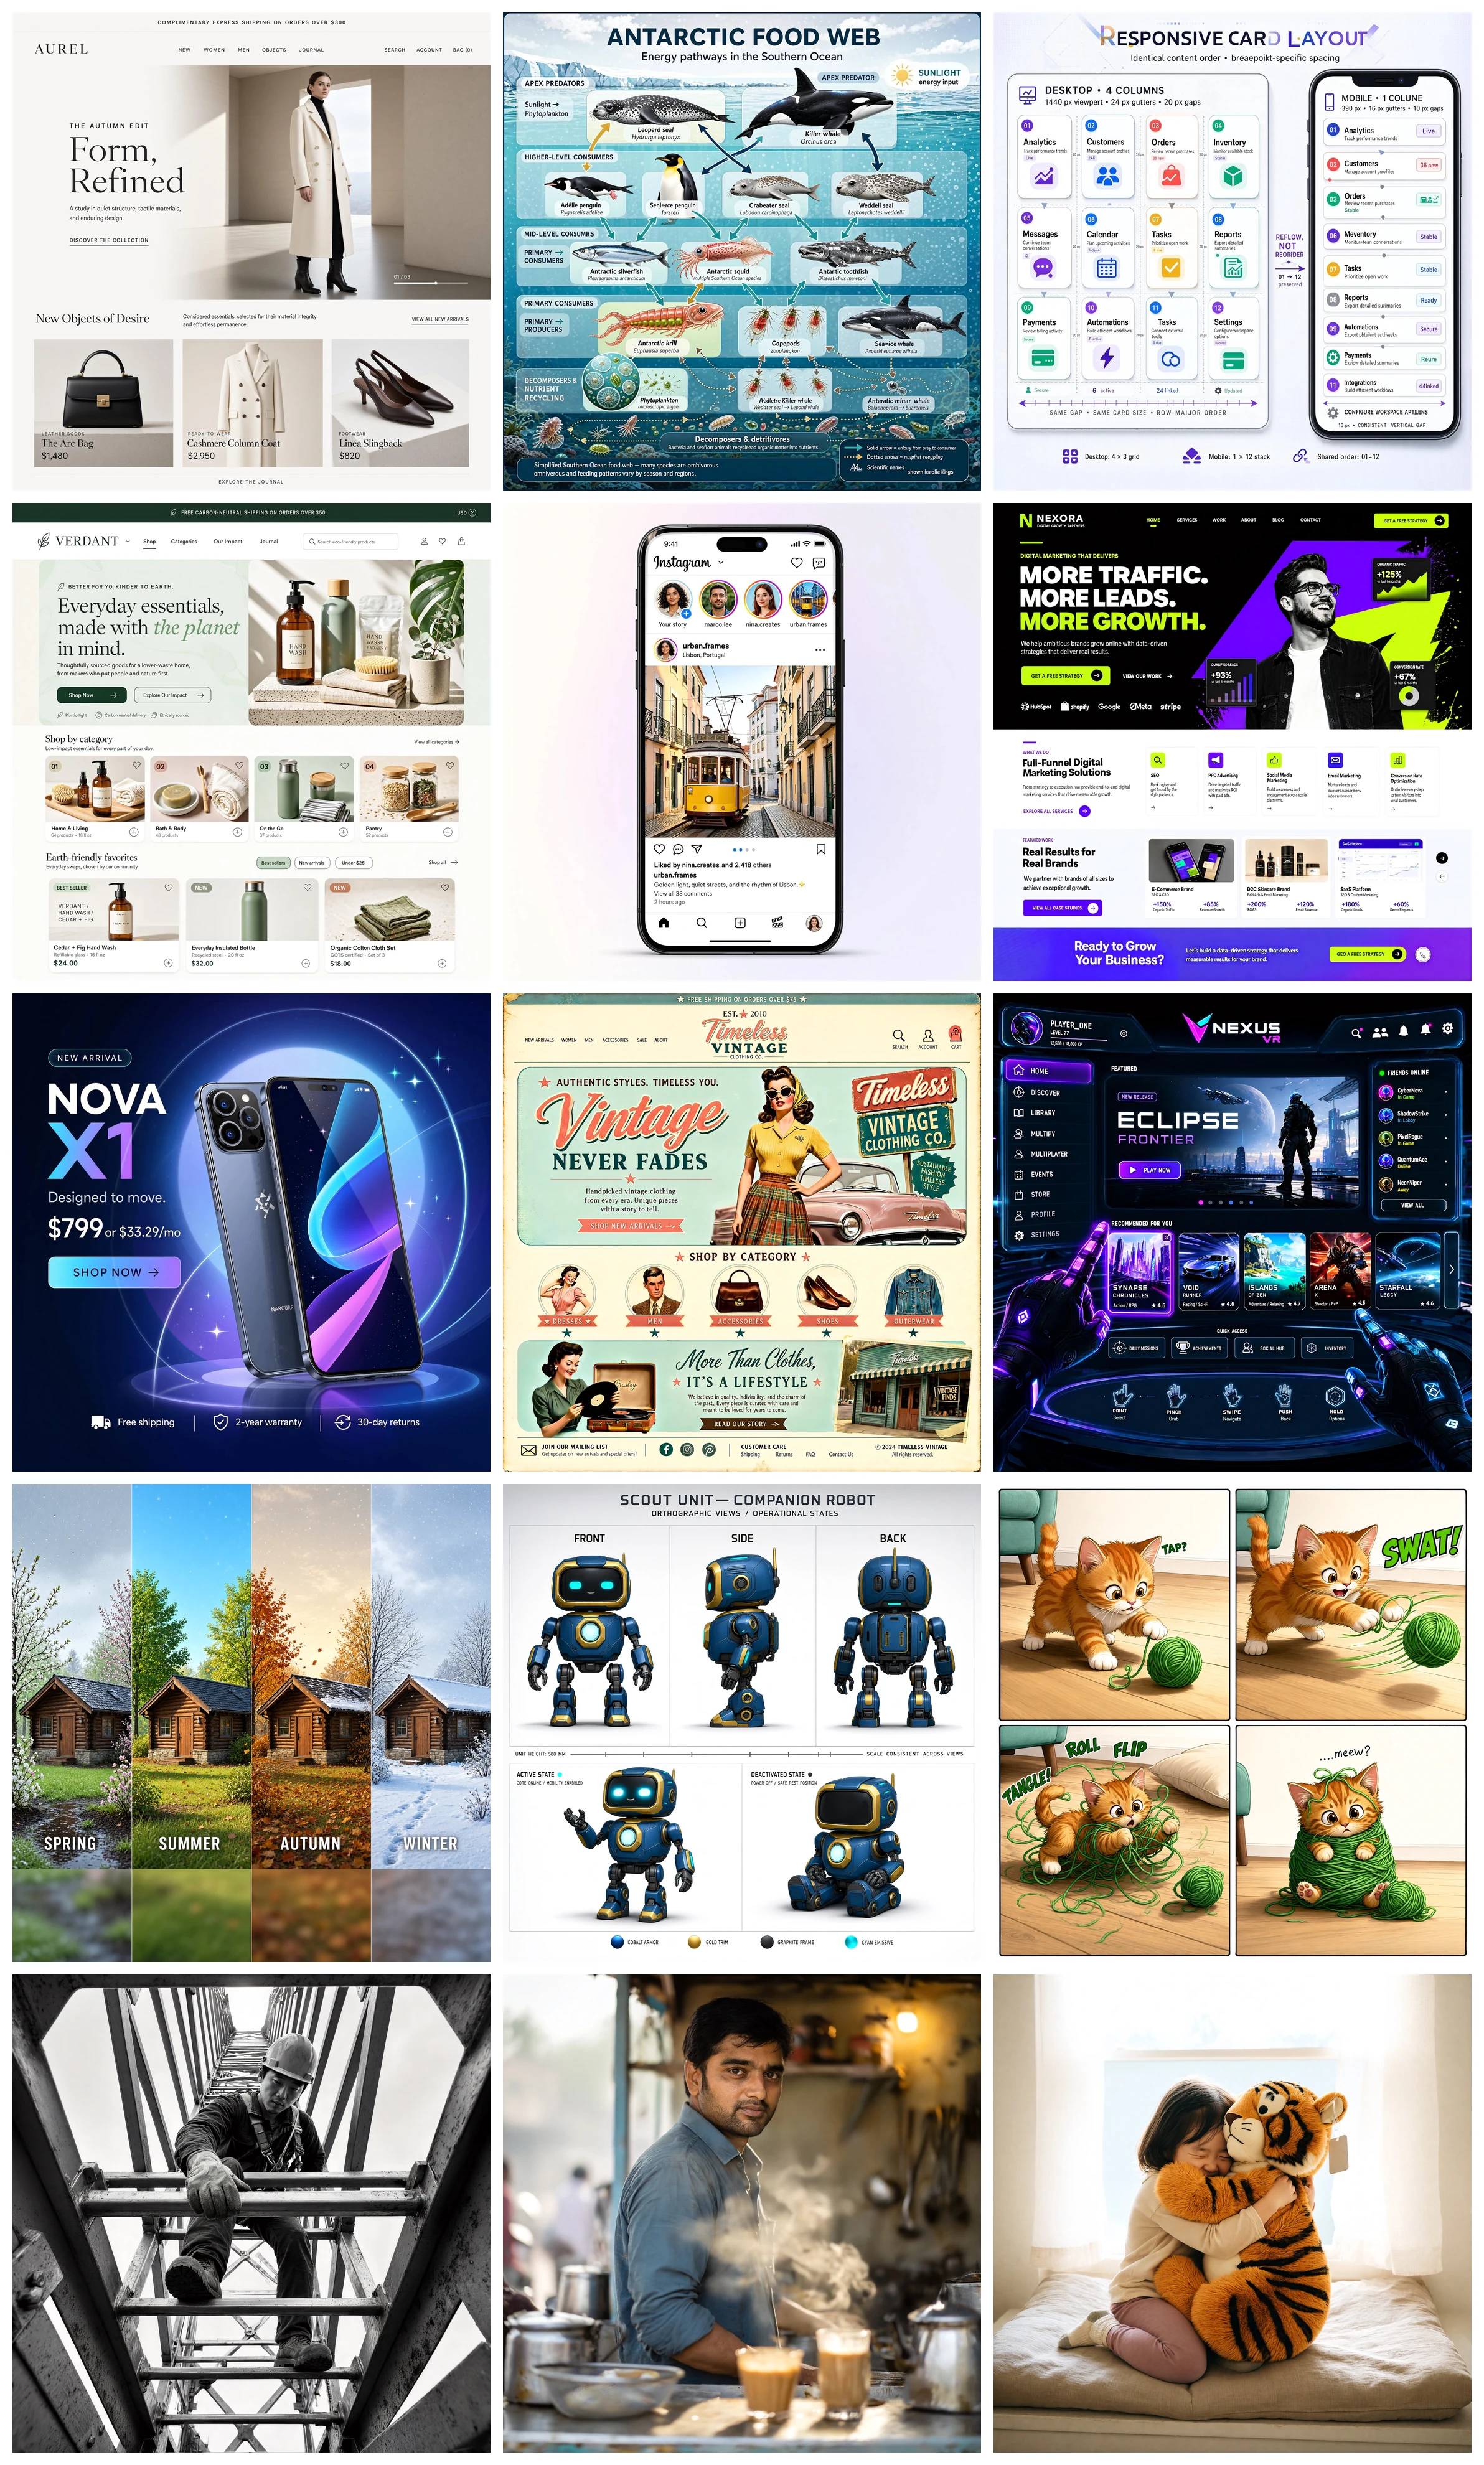
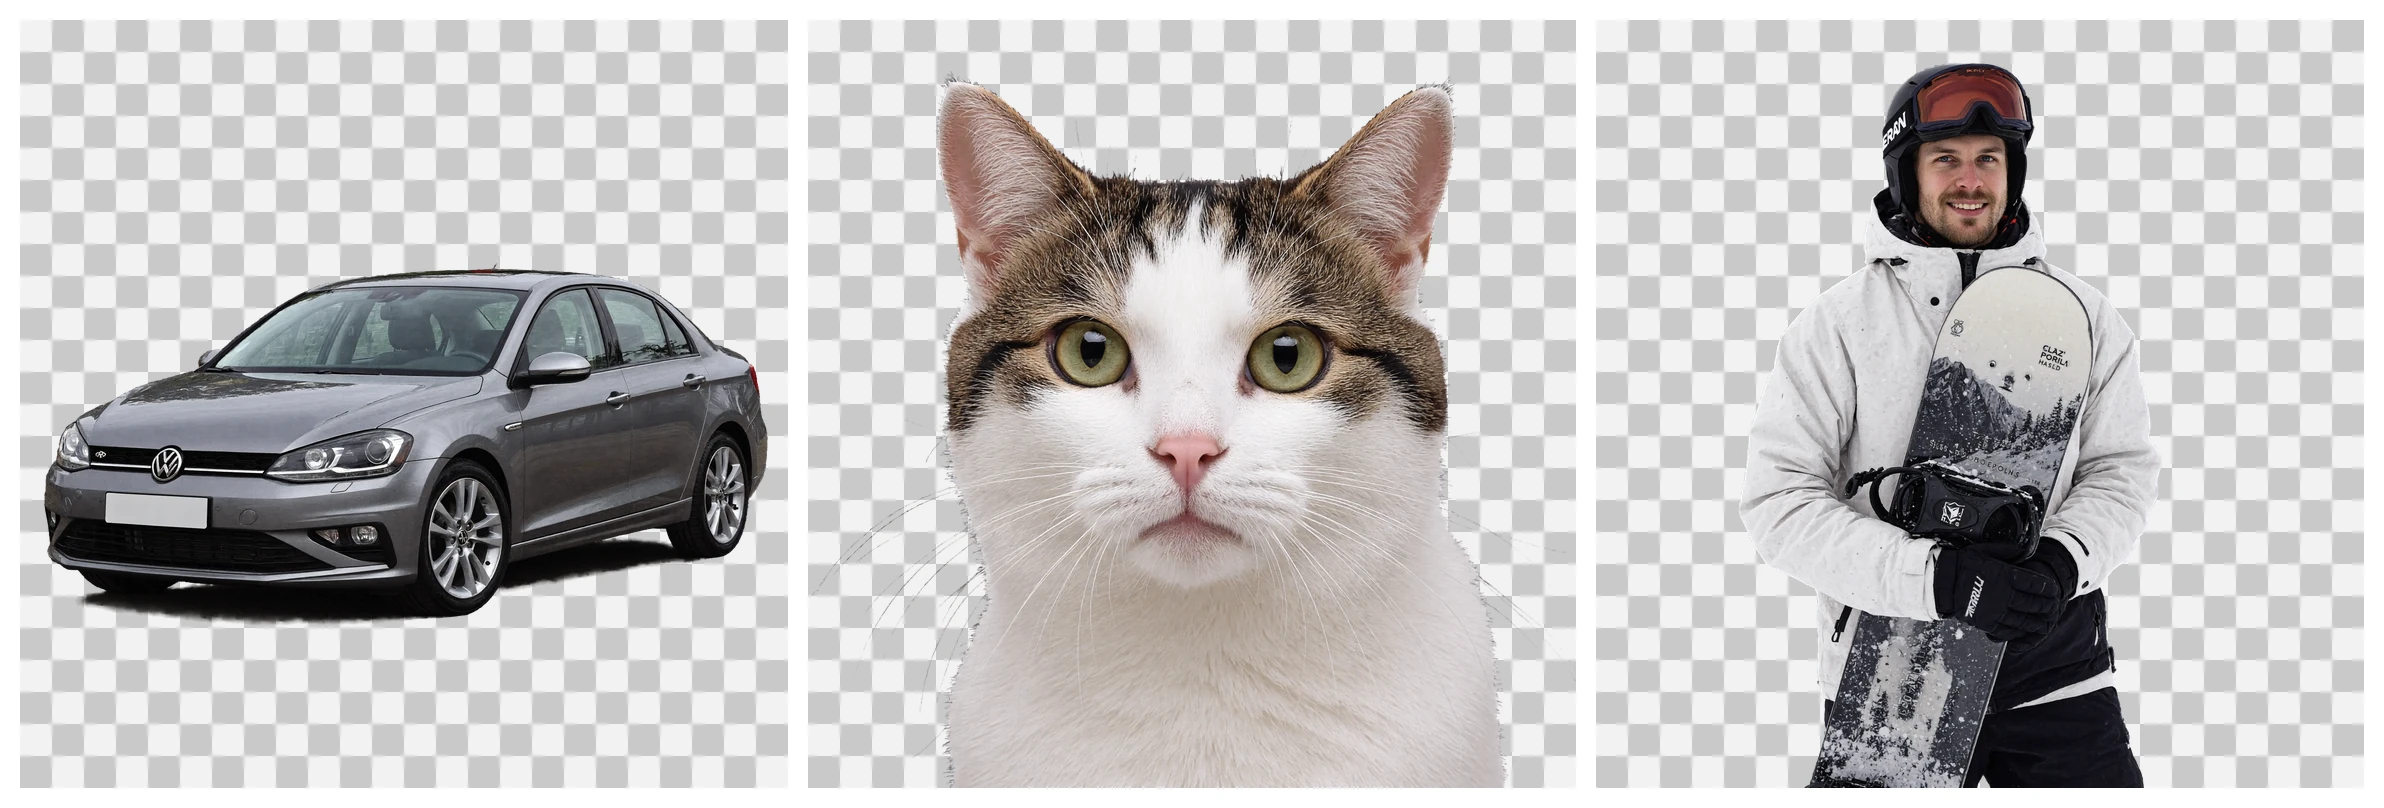
Ming-Image-0.1-Design is a 6B text-to-image model for UI, infographics, posters, and other text-rich visual designs. It generates complete visual compositions and supports RGBA output with transparent backgrounds.
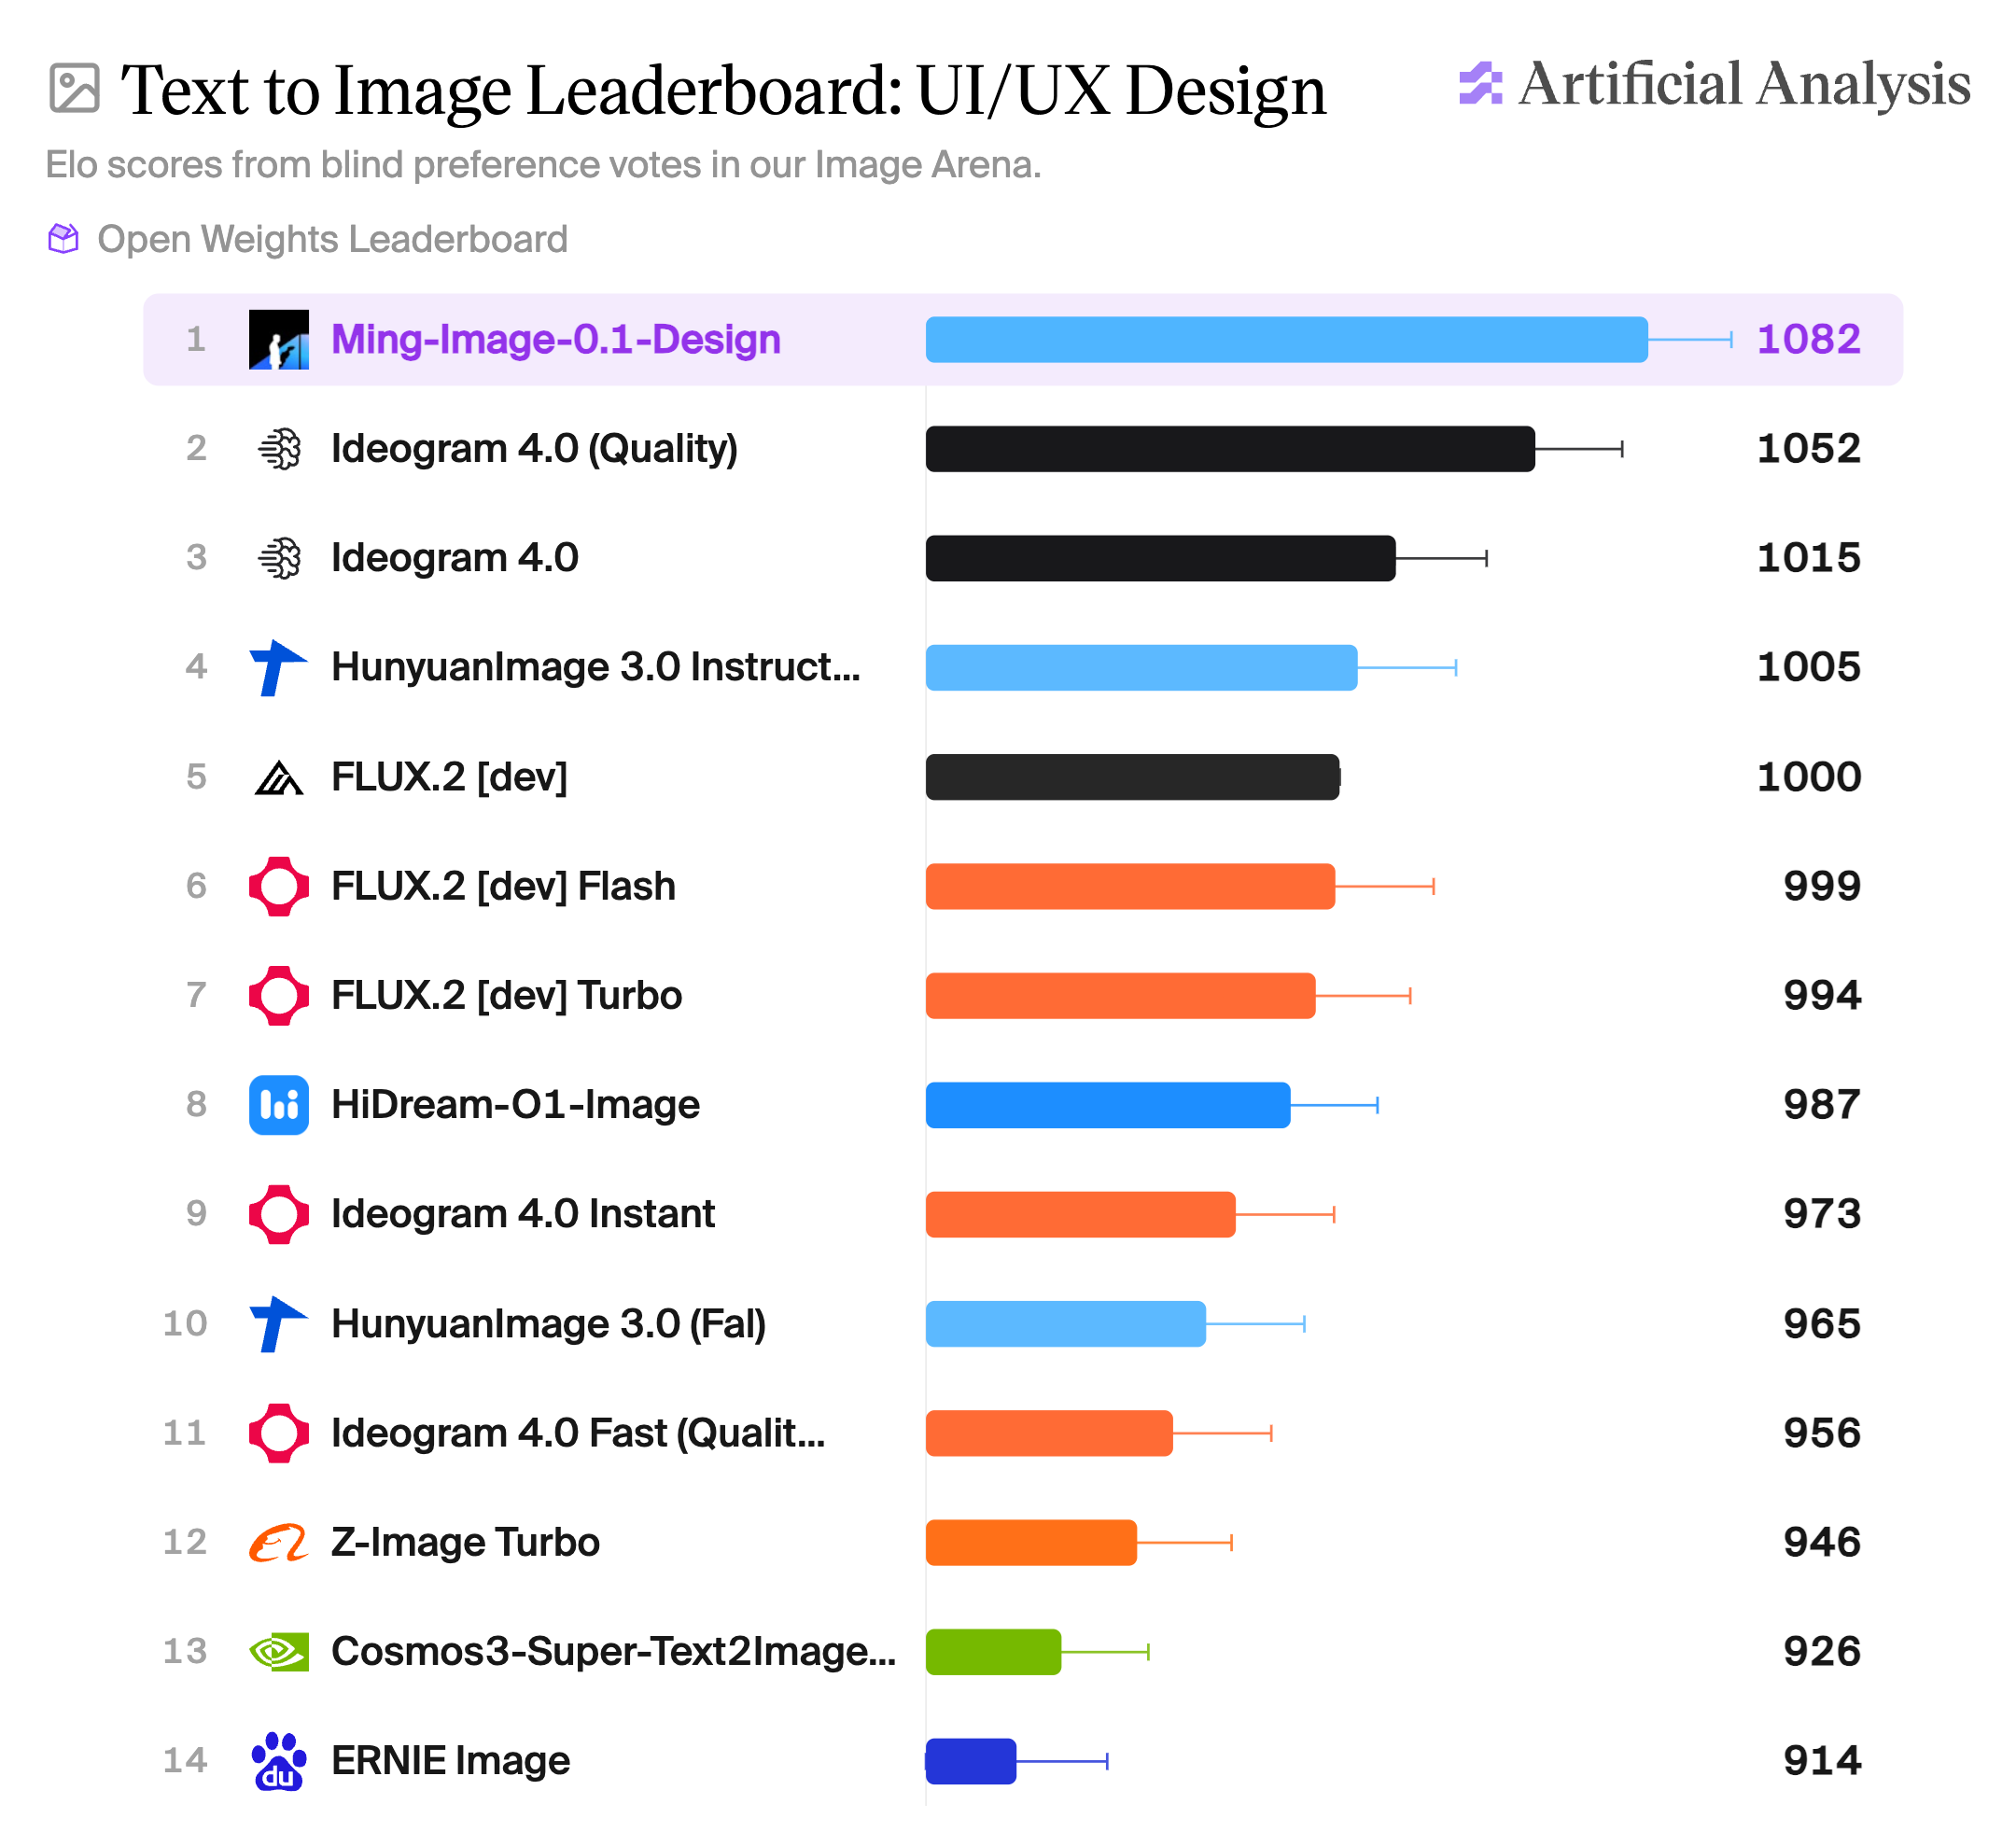
UI/UX Design leaderboard

Quick Start
Use the companion Ming-Image repository for installation and inference:
git clone https://github.com/inclusionAI/Ming-Image
cd Ming-Image
pip install -r requirements.txt

python infer.py \
  --model inclusionAI/Ming-Image-0.1-Design \
  --task text-to-image \
  --prompt assets/t2i_four_seasons_cabin_prompt.json \
  --resolution 2048 \
  --output-dir outputs/t2i
Prompt enhancement (PE) can use Ling-3.0-flash-VL or qwen3.8-27B; see
text-to-image prompt rewriting.
Transparent-background generation
For transparent-background generation, prepend exactly one of the recommended RGBA phrases. See the transparent-background generation tip.
Deployment
We recommend the following inference frameworks to serve the model:
- vLLM-Omni: see the recipes and installation guide.
Recommended settings
- Resolution: 2048 x 2048 (recommended), or 1024 x 1024 for faster generation.
- Sampling steps: 12.
- CFG scale: 1.0.
- Precision: BF16.
- Hardware: one CUDA GPU with 80 GiB VRAM (validated configuration).
The public inference code maps text-to-image resolution requests to the supported 1024 or 2048 bucket.
Gallery
Text-to-image

Transparent-background text-to-image

The checkerboard is used only to preview transparency; it is not part of the generated RGBA images.
License
This model is released under the MIT License.
Derived on Sep 24, 2026 from Hugging Face at revision 208087ad, README.md .
36 files, 52.9 GB. Every download is checked against its address.